DeepSeek-V4.1-Flash-1017-AZ-Focus
DeepSeek's October update to V4.1 Flash, with the second-guessing taken out. About a third less thinking across every benchmark we ran, with the same scores as the original: our closest match to stock yet, and a drop-in replacement for it.
Same answers, less second-guessing
DeepSeek-V4.1-Flash-1017 is a stronger and already more concise model than the original V4.1 Flash, but its thinking still carries a lot of hesitation: "Wait…", "Hmm, maybe…", re-deriving answers it already had. We optimised the model's weights against that habit, while leaving alone the checking it does as an agent and on hard maths. On held-out maths, it backtracks about six times less often, and reaches the same 95.0% accuracy.
Less thinking at every effort setting
DeepSeek-V4.1-Flash-1017 has a reasoning-effort dial from 1 to 100, so the fair question is: why not just turn it down? We measured both models at the same settings. At every setting, AZ-Focus thinks 27–49% less, with accuracy level on average: the same on MMLU-Pro, and about half a point lower on BIG-Bench Hard.
One run per setting; single runs on a few hundred questions move by a point or two either way. At effort 25, AZ-Focus answers MMLU-Pro with 45% less thinking than the original at the same setting, at the same accuracy.
Across benchmarks, at the default setting
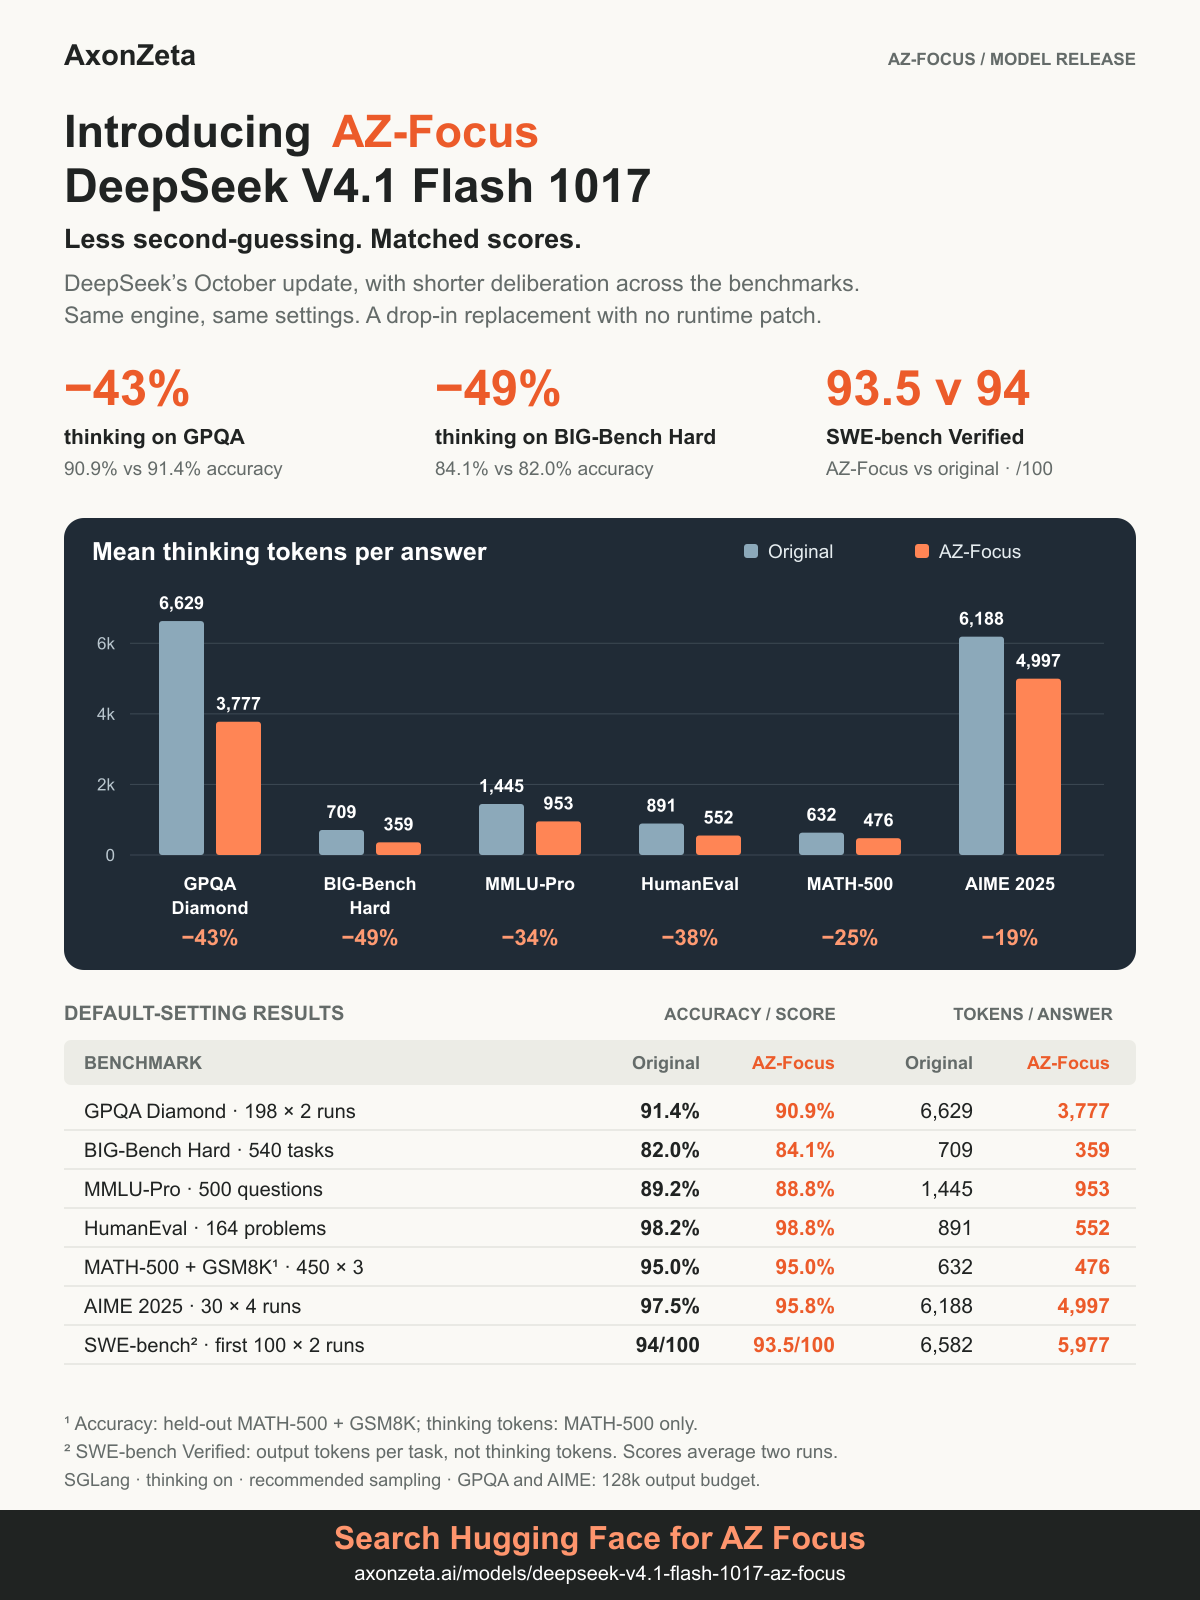
DeepSeek-V4.1-Flash-1017 vs AZ-Focus, both served the same way (SGLang, thinking on, DeepSeek's recommended sampling). GPQA Diamond and AIME were run with a 128k-token output budget for both models. None of these benchmarks was used to build the model.
| Benchmark | Original | AZ-Focus | Thinking original | Thinking AZ-Focus | Change |
|---|---|---|---|---|---|
| Reasoning & knowledge | |||||
| GPQA Diamond198 graduate-level science questions, 2 runs | 91.4% | 90.9% | 6,629 | 3,777 | 43% less |
| BIG-Bench Hard540 logic & reasoning tasks | 82.0% | 84.1% | 709 | 359 | 49% less |
| MMLU-Pro500 questions, 14 subjects | 89.2% | 88.8% | 1,445 | 953 | 34% less |
| Coding | |||||
| SWE-bench Verifiedfirst 100 tasks, agentic (mini-SWE-agent), 2 runs (output tokens per task) | 94/100 | 93.5/100 | 6,582 | 5,977 | 9% less |
| HumanEval164 problems | 98.2% | 98.8% | 891 | 552 | 38% less |
| Maths | |||||
| MATH-500 + GSM8K450 held-out problems, 3 runs (tokens: MATH-500) | 95.0% | 95.0% | 632 | 476 | 25% less |
| AIME 202530 competition problems, 4 runs | 97.5% | 95.8% | 6,188 | 4,997 | 19% less |
Our closest match yet
Every benchmark lands within run-to-run variation of the original, including agentic coding: 94 and 93 tasks resolved over two SWE-bench runs, against 94 and 94, with no empty patches.
Answers aren't shortened
The change is to deliberation, not to the answers. With thinking switched off, output length on code, JSON, formatting and writing is unchanged.
Sooner, not slower
Speed per token is unchanged, so fewer tokens means earlier answers and more work from the same hardware.
A drop-in replacement
Same architecture, tokenizer, chat template, file layout and size as DeepSeek-V4.1-Flash-1017, in the same MXFP4/FP8 formats. Serve it with the same engine and settings: no adapter, patch or extra code. Use DeepSeek's recommended sampling (temperature 1.0, top-p 0.95); the difference shows in thinking mode.
Running the original V4.1 Flash rather than 1017? Use DeepSeek-V4.1-Flash-AZ-Focus.
Limitations
- Hard competition maths is slightly behind: AIME 2025 115 vs 117 of 120 answers correct across 4 runs, and MATH level 5 87.6% vs 89.6% across 3 runs. Both are within run-to-run variation, but if olympiad-style maths is your main use, you may prefer the original.
- Measured on reasoning, knowledge, science, code, agentic coding and maths benchmarks. Long multi-hour agent sessions, other languages and very long contexts haven't been measured separately yet.
- If you need the model's full self-verification trail, use the original.
MIT licence, as for the original. Based on DeepSeek-V4.1-Flash-1017 by DeepSeek-AI.
Want to build on this?
We're an independent AI lab, looking for a few partners to build with at the frontier.