Low-bit models think longer.
Quantization is how big models fit on one machine. It also has a cost that accuracy scores hide: a squeezed reasoning model often reaches the same answers, but second-guesses for longer to get there. We measured it for the weights and for the KV cache, and checked what AZ-Focus does in each case.
The finding we built on
Lotfi et al., Quantized Reasoning Models Think They Need to Think Longer, but They Do Not (May 2026), showed on models up to 32B that aggressive weight quantization lowers accuracy and lengthens chain-of-thought. In up to 52% of the quantized models' failures, the model reached the correct answer mid-reasoning and didn't commit to it. The damage concentrates on hesitation tokens ("Wait", "But", "Alternatively"), and a simple decode-time penalty on those tokens cuts chain-of-thought by 12–23%. We asked two follow-up questions: does it hold for a much larger MoE model, and does it also happen when you quantize the KV cache instead of the weights?
1. Weights at 2 bits: GLM-5.3-Flash
GLM-5.3-Flash at 2.05 bits per weight is 87 GB, small enough for one 128 GB DGX Spark. We built AZ-Focus at turboderp's 2.05 bpw settings and a stock quant with identical settings, and ran both on the same server:
The stock quant spirals: on one MMLU-Pro question it thought for 41,616 tokens where AZ-Focus reached the same correct answer in 396, and on one GPQA question it ran to the 128k limit without answering. On knowledge and reasoning AZ-Focus uses 65% less thinking, scores within one answer of stock (47 vs 48 of 58), and answers more questions correctly up to a 32k budget. Competition maths is the exception: on AIME both quants think at length, and AZ-Focus solved 3 of 6 to stock's 4.
2. The KV cache at 8, 4 and 2 bits: Qwen3.8-Flash-Next
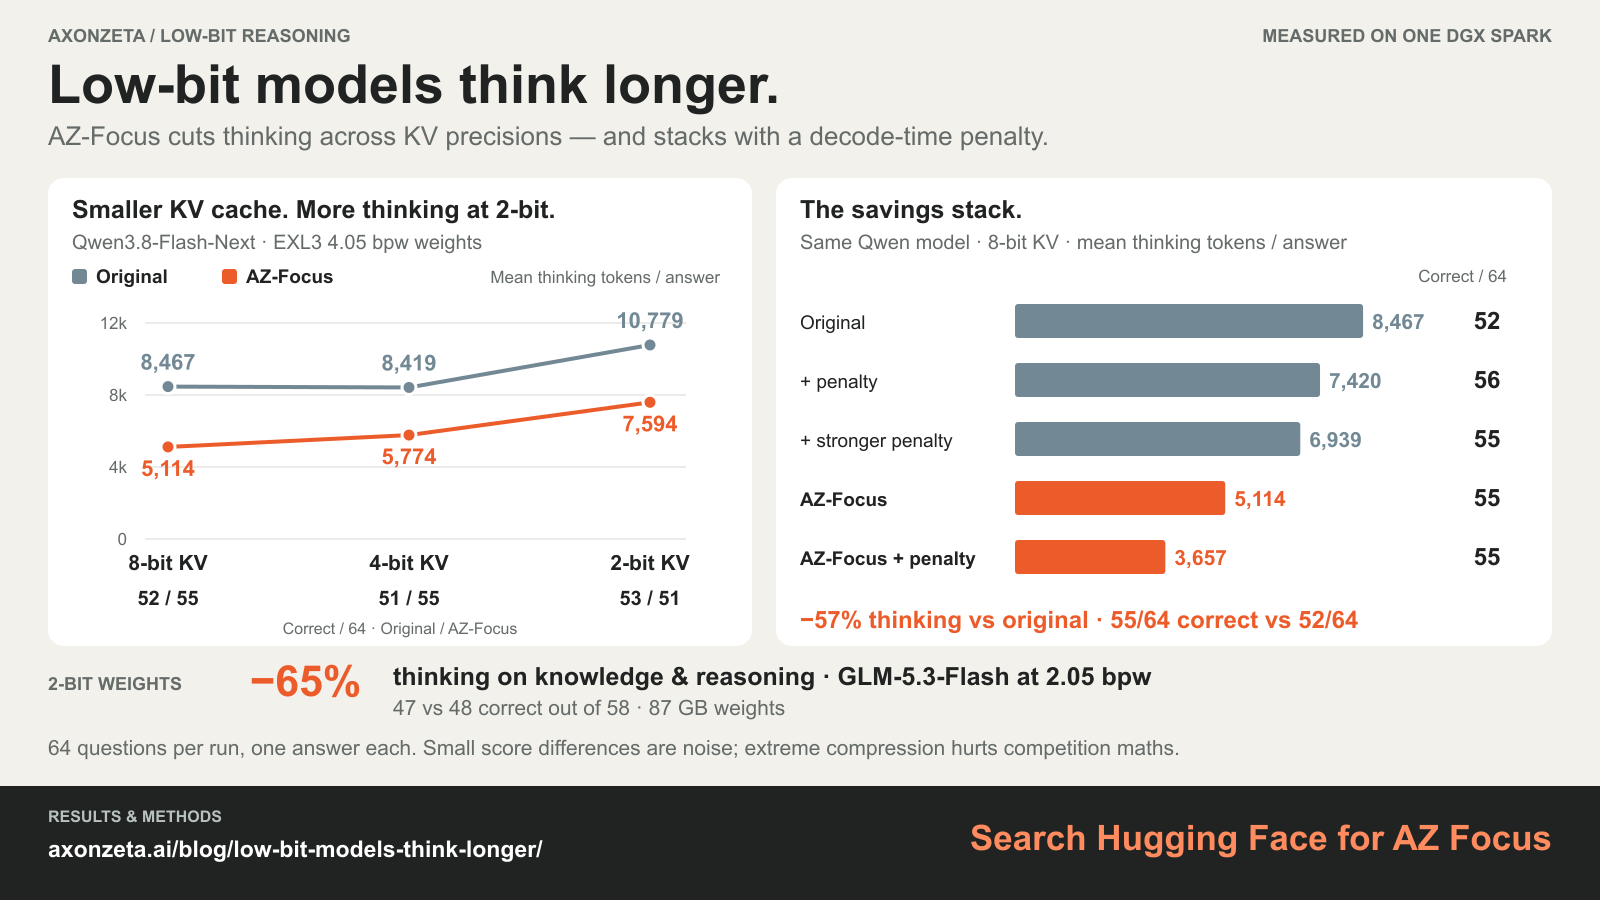
The KV cache is the model's working memory for the conversation so far, and on long contexts it can rival the weights in size. Compressing it is the other way to fit more on one machine. We took Qwen3.8-Flash-Next at 4.05 bits per weight (EXL3), original and AZ-Focus, and ran the same 64 questions with the KV cache at 8, 4 and 2 bits per value, on the same server and hardware:
- 4-bit KV is free. The original model's thinking changed by −1% and its score by one answer. AZ-Focus stayed at 55 correct. Halving the KV cache from 8 to 4 bits cost nothing we could measure.
- 2-bit KV makes the original model think 27% longer. It's the same direction as weight quantization, though milder: the score held (53 of 64), but the extra thinking went mostly to GPQA and AIME.
- AZ-Focus keeps its lead on thinking, 30–40% below the original at every KV setting, but at 2 bits it loses ground on competition maths: AIME fell from 6 of 6 to 4 (the original fell to 5), with one answer running to the limit. Within a 4k–8k token budget the two models are level at 2-bit KV, where AZ-Focus was 4 answers ahead at 8-bit.
3. Against the decode-time penalty
Lotfi et al.'s fix needs no new model: lower the probability of the hesitation markers while decoding. We applied it at the paper's settings (a penalty of 2 on 50 markers), and a stronger version that also penalises 10 paragraph openers by 4, through the standard logit_bias parameter. Same 64 questions, 8-bit KV, one answer each:
| Correct, of 64 | Thinking per answer | vs original | GPQA thinking | |
|---|---|---|---|---|
| Original | 52 | 8,467 | — | 13,924 |
| Original + penalty | 56 | 7,420 | -12% | 14,185 |
| Original + stronger penalty | 55 | 6,939 | -18% | 8,623 |
| AZ-Focus | 55 | 5,114 | -40% | 7,133 |
| AZ-Focus + penalty | 55 | 3,657 | -57% | 4,714 |
- The penalty works as published: 12–18% less thinking on the original model, in line with the 12–23% the paper reports, and no loss of accuracy.
- It mostly trims the easy questions. At the paper's setting, the original model's thinking on GPQA and AIME didn't fall at all; only the stronger penalty shortened GPQA.
- AZ-Focus alone saves more (−40%) at the same score, and the two stack: AZ-Focus with the penalty answered 55 of 64 with 57% less thinking than the original, including a third of the original's thinking on GPQA.
What we take from it
Both kinds of compression push reasoning models the same way: at the extreme, they second-guess more. Weights are the bigger lever: at 2 bits per weight, AZ-Focus's gain is large on knowledge and reasoning. For the KV cache, 4 bits is free and 2 bits starts to cost thinking time. In both cases, competition maths is where extreme compression hurts AZ-Focus most, and we'd keep a higher-precision setup for olympiad-style problems.
For one DGX Spark, the setup we'd recommend from these runs: 4-bit weights, a 4-bit KV cache, and AZ-Focus. That keeps the memory savings that are free, avoids the ones that start to cost thinking, and removes most of the second-guessing that's left. A decode-time penalty is a cheap extra on top.
What this does and doesn't show
- One answer per question on 64 questions per run: accuracy differences of a couple of answers are noise; the thinking-length changes of 25% and more are the signal.
- KV results are for one model and engine (Qwen3.8-Flash-Next, exllamav3's quantized cache). Other engines quantize the KV cache differently, and models with more full-attention layers keep a larger cache.
- The penalty comparison is one model (Qwen3.8-Flash-Next) at 8-bit KV; we didn't tune the penalty strength beyond the paper's setting and one stronger variant.
References
- S. Lotfi et al., Quantized Reasoning Models Think They Need to Think Longer, but They Do Not, arXiv:2606.00206, May 2026.
- S. Zhou et al., When More Thinking Hurts: Overthinking in LLM Test-Time Compute Scaling, arXiv:2604.10739, April 2026.
- Models: GLM-5.3-Flash-AZ-Focus (including the 2.05 bpw build) and Qwen3.8-Flash-Next-AZ-Focus (EXL3 4.05 bpw).