Same speed, half the wait.
Tokens per second is the number everyone shares. But when you ask a reasoning model a question, what you wait for is the answer, and that depends on how many tokens it spends thinking first. We ran GLM-5.3-Flash and our GLM-5.3-Flash-AZ-Focus side by side on two DGX Sparks, on identical software, and measured both.
The setup
- Hardware: 2× NVIDIA DGX Spark (GB10, 128 GB each), tensor parallel across both, RoCE over ConnectX-7.
- Software, identical for both models: Mia's GLM-5.3-Flash TensorFold kit v1.10 (TensorFold v0.6.0 with the kit's patch stack), served from the kit's published image, pinned by digest, at its default settings.
- Models: the kit's stock EXL3 checkpoint (routed experts at 4 bits, the rest BF16) and our GLM-5.3-Flash-AZ-Focus EXL3, same format and layout.
- Drafters: both of the kit's options: its default DFlash2 drafter, and the model's built-in MTP head.
- Fair comparison: stock and AZ-Focus ran at the same time on separate pairs of Sparks, with nothing else on them.
1. The same speed
We used RigMark, the serving benchmark many DGX Spark recipe authors now publish with, at its standard settings (low effort, as in the community's reference receipts):
| Model | Drafter | Prose | Code | Structured | Prefill 32K | 4 users |
|---|---|---|---|---|---|---|
| GLM-5.3-Flash (stock) | DFlash2 | 44.4 | 75.6 | 102.4 | 2,012 | 105.6 |
| AZ-Focus | DFlash2 | 43.1 | 74.5 | 102.8 | 2,032 | 106.4 |
| GLM-5.3-Flash (stock) | MTP | 44.8 | 64.4 | 70.6 | 1,991 | 53 |
| AZ-Focus | MTP | 43.1 | 64.2 | 70 | 1,985 | 53.5 |
Tokens per second (decode, single request; prefill at 32K tokens; aggregate with 4 requests, 256-token cap). Rates include streamed reasoning.
At these settings everything is within noise: decode, prefill and multi-user throughput. AZ-Focus is the same architecture and size, so this is what you'd hope for. It's also good news for the drafters: they were trained on stock GLM-5.3-Flash's outputs, and they accept AZ-Focus's tokens just as well.
2. Half the tokens, so half the time
Then the question that matters: how long until the answer is finished? We sent the same 60 questions (30 from MMLU-Pro, 30 from BIG-Bench Hard) to both models at GLM-5.3-Flash's default max effort, with Z.AI's recommended sampling and no output cap that could cut reasoning short.
AZ-Focus used 743 tokens per answer against 1,589, and finished the set in about half the time, with one user or four. Both answered about as many questions correctly (52 and 50 of 60); on our full benchmarks AZ-Focus matches the original on reasoning and knowledge (see the model page).
One detail we liked: the token counts were identical with either drafter. TensorFold's speculative decoding is exact, so the drafter changes how fast tokens arrive, never which tokens you get.
And the pelican test
No benchmark post is complete without a pelican riding a bicycle. Same prompt, thinking on at max effort for both, two requests at once on each pair of Sparks:
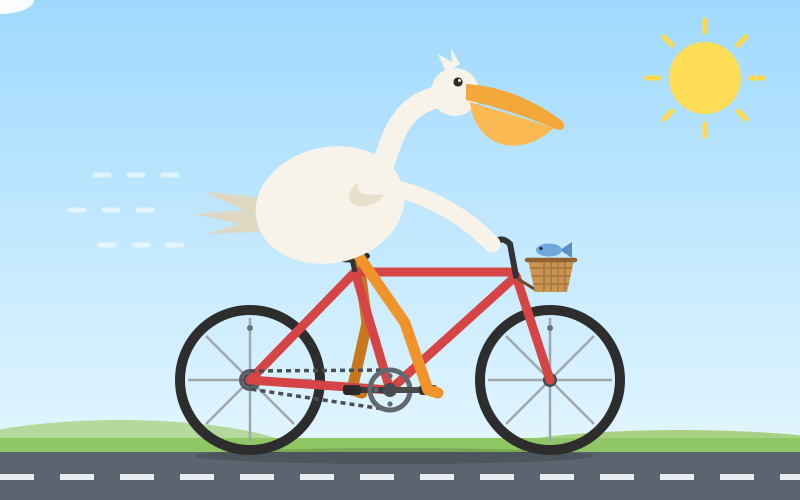
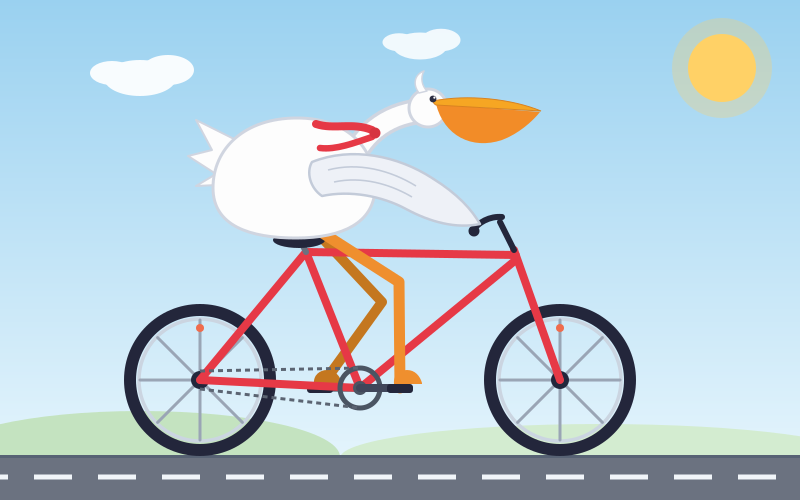
Both are good pelicans (one of each shown). The pair from stock took 113,154 tokens; the pair from AZ-Focus took 74,218, about a third fewer. That fits the benchmark: a detailed SVG is mostly writing rather than deliberating, so the saving is smaller than on reasoning questions, but the drawing doesn't suffer.
Why a token cap can hide this
RigMark caps each answer at 8,192 tokens by default, reasoning included. At max effort stock GLM-5.3-Flash often thinks for longer than that (up to 18,800 tokens on a RigMark coding prompt in our runs), so with the default cap both models get cut off at the same length and look identical. For our max-effort RigMark runs we raised the cap to 32,768 tokens (three samples per workload) and published those receipts too:
| Max effort, DFlash2 | Prose | Code | Structured |
|---|---|---|---|
| GLM-5.3-Flash (stock): time to last token | 151.5 s | 247.7 s | 10.5 s |
| AZ-Focus: time to last token | 60.6 s | 175.8 s | 10.5 s |
| Decode speed, stock / AZ-Focus (tok/s) | 68.2 / 48.6 | 73.0 / 71.8 | 102.2 / 102.4 |
One honest wrinkle: at max effort the DFlash2 drafter decoded AZ-Focus's prose more slowly than stock's. Stock's long prose reasoning seems to be easier for the drafter to predict. AZ-Focus still finished those answers 2.5× sooner, because it wrote far fewer tokens, and at the standard low-effort settings prose speed is the same.
What this does and doesn't show
- It's one Spark pair size (two Sparks, TP2). Three-Spark (TP3) results follow in a second post.
- The time-to-complete set is 60 questions with one sample each, so accuracy differences of a couple of questions are noise. The speed-up comes from the token counts, which are stable.
- The gain is largest at max and high effort, where most of the hesitation is. At low effort both models think briefly and finish in similar time.
- Agentic coding is about 3 points below the original on SWE-bench Verified in our runs; details on the model page.
- DFlash2, the kit's default drafter, is licensed for non-commercial use only. We used it here only to measure, as the kit ships it; the MTP results show the same picture with a fully open drafter.
Reproduce it
Both models, the kit and RigMark are public. Each RigMark receipt records the image digest, checkpoint revision, drafter and settings of its run. Both servers report the kit's model name, GLM-5.3-Flash-EXL3; the Checkpoint line on each card says which model it was.
- GLM-5.3-Flash, DFlash2, low effort (JSON)
- GLM-5.3-Flash, DFlash2, max effort (JSON)
- GLM-5.3-Flash, MTP, low effort (JSON)
- GLM-5.3-Flash, MTP, max effort (JSON)
- AZ-Focus, DFlash2, low effort (JSON)
- AZ-Focus, DFlash2, max effort (JSON)
- AZ-Focus, MTP, low effort (JSON)
- AZ-Focus, MTP, max effort (JSON)
Time to complete: ttc.py (Python standard library only), the 60 questions, and the results for each run (stock and AZ-Focus with DFlash2 and one user; the others are alongside them in the same folder).
Thanks to Ash Hart for TensorFold, to Mia for the GLM-5.3-Flash TensorFold kit, and to Alex Ellis for RigMark.